


Hybrid AI Filmmaking: Taking Control of Graybox Production Workflows
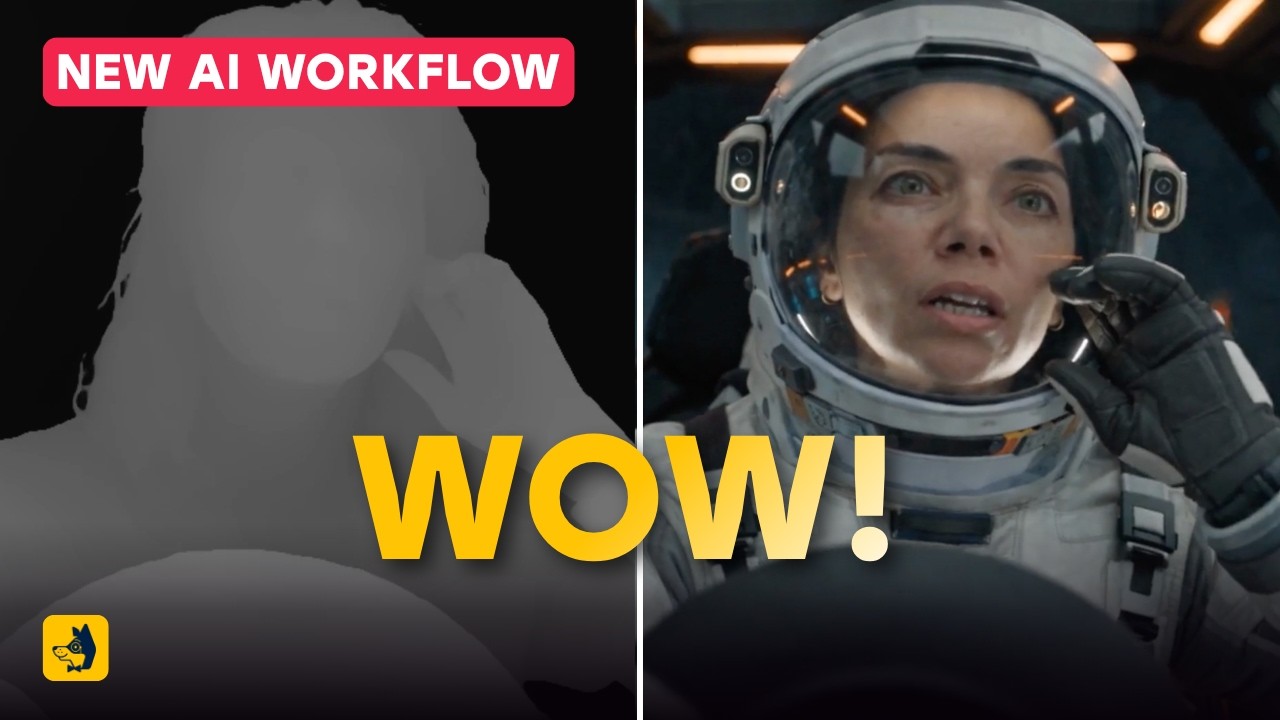
While graybox production allows creators to shoot footage in plain, flatly lit environments and transform them using artificial intelligence, standard generative methods often suffer from severe environmental inconsistencies. Simple text prompting leaves background elements to chance across successive renders, making scene continuity difficult to maintain in a narrative film.
Overcoming these generative limitations requires establishing precise structural and visual anchors before rendering final video sequences.
By exporting an initial frame, stylizing it through image-to-image models, and leveraging midjourney style references, filmmakers establish precise aesthetic control over color grading, lighting, and environmental detail.
Integrating depth maps into video aggregators further locks spatial relationships and character motion into place, bridging the gap between raw studio plates and filmic, screen-ready visuals.
Depth Maps and Structural Continuity
Utilizing depth maps as motion references preserves spatial geometry, ensuring actor movement and camera trajectories remain accurate throughout dynamic shots.
Combining black-and-white depth passes with original live-action footage helps AI models retain actor likeness and physical contact interactions without introducing distracting distortion or unwanted scene drift.
Intentional Studio Lighting Setup
Relying entirely on completely flat lighting during greybox capture can yield flatter generative results. Mimicking target illumination on set—such as placing overhead diffusion screens for moonlight—significantly improves the realism of downstream AI renders.
Pre-lighting physical spaces to match the intended atmosphere ensures that shadows and highlight roll-offs translate naturally into complex sci-fi, fantasy, or period environments.
Practical Production Advice: Always generate multiple initial stylized keyframes and evaluate different image-generation models before committing to video generation. Small variations in base image contrast, shadow placement, and color hue heavily dictate how generative video models interpret physical volume and ambient light across an entire sequence.
Video and images via Curious Refuge


0 comments:
Post a Comment